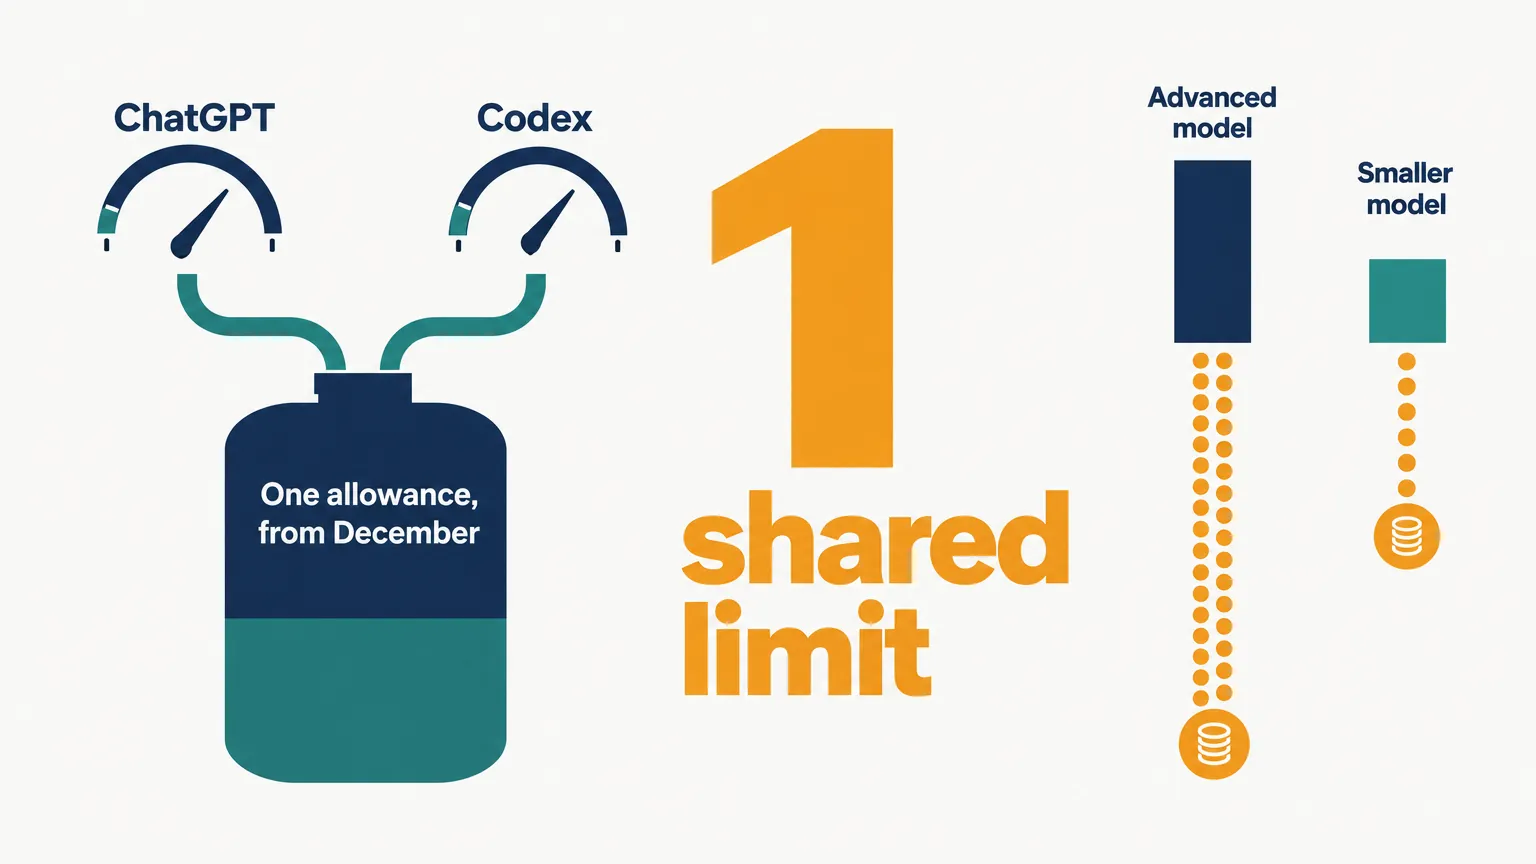
OpenAI will pool the usage on ChatGPT’s paid plans. Starting in December, Plus, Pro and Business subscribers get one allowance that covers both ChatGPT and Codex, measured in tokens instead of separate limits. The change sits in a help-center article, Understanding ChatGPT and Codex usage limits, updated on October 31, 2026. We found no OpenAI blog post or X post announcing it.
The article opens with the scope: “Starting in December, Plus, Pro, and Business plans’ usage allowance will be shared across ChatGPT and Codex as we bring the agentic capabilities of Work into the main ChatGPT experience.” Users spotted the page on X the same afternoon, and one post summing it up passed 89,000 views within six hours.
On this page · 8 sectionsOpen
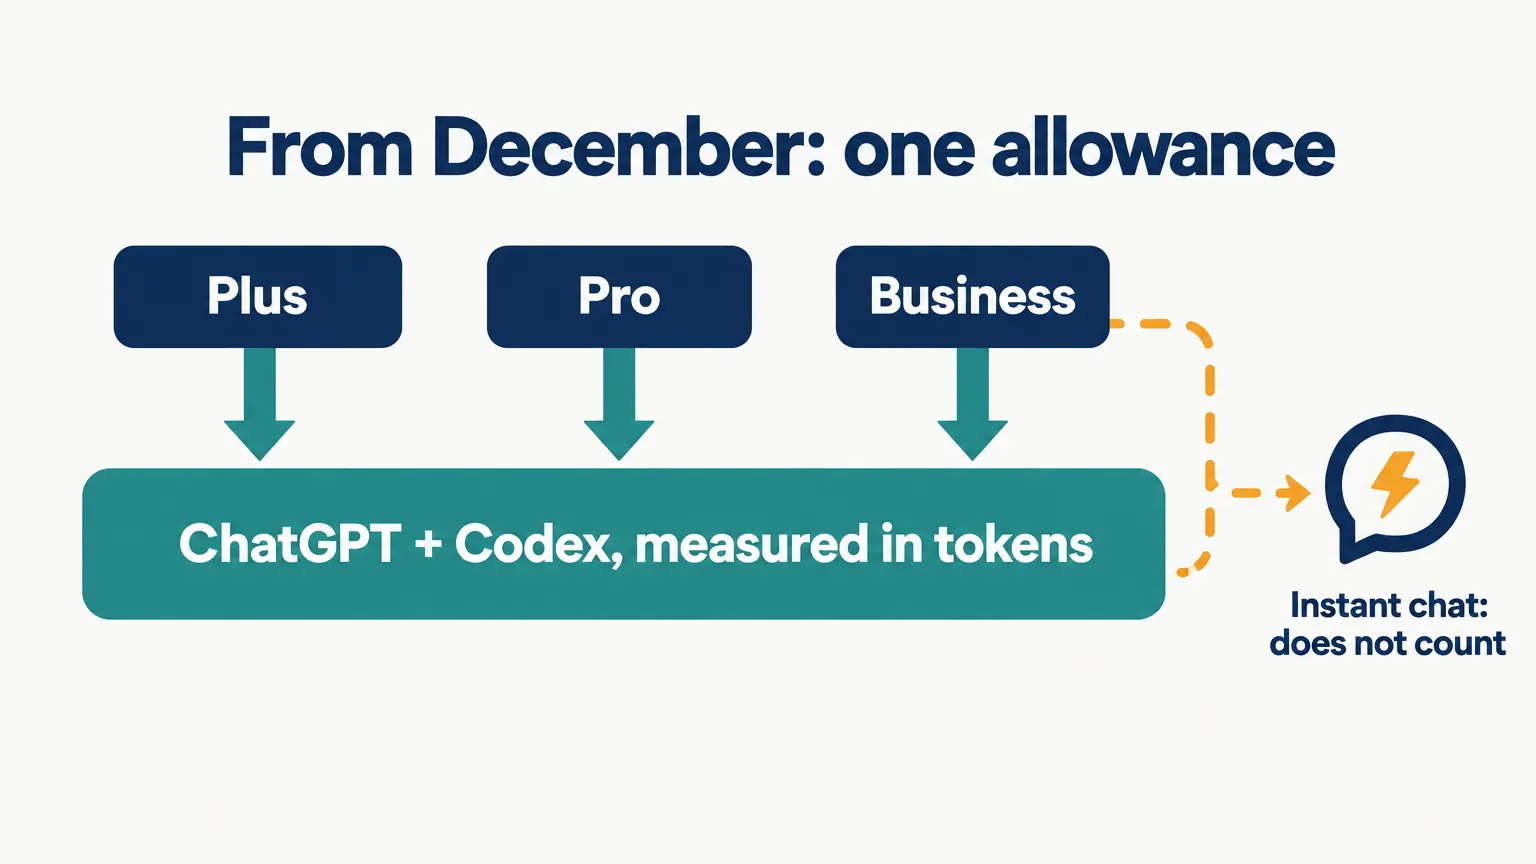
 From December, Plus, Pro and Business plans will share one usage allowance across ChatGPT and Codex, per OpenAI’s help center.
 Usage will be measured in tokens, so more advanced models and harder tasks use more of the allowance.
 Instant chat will not draw from the allowance.
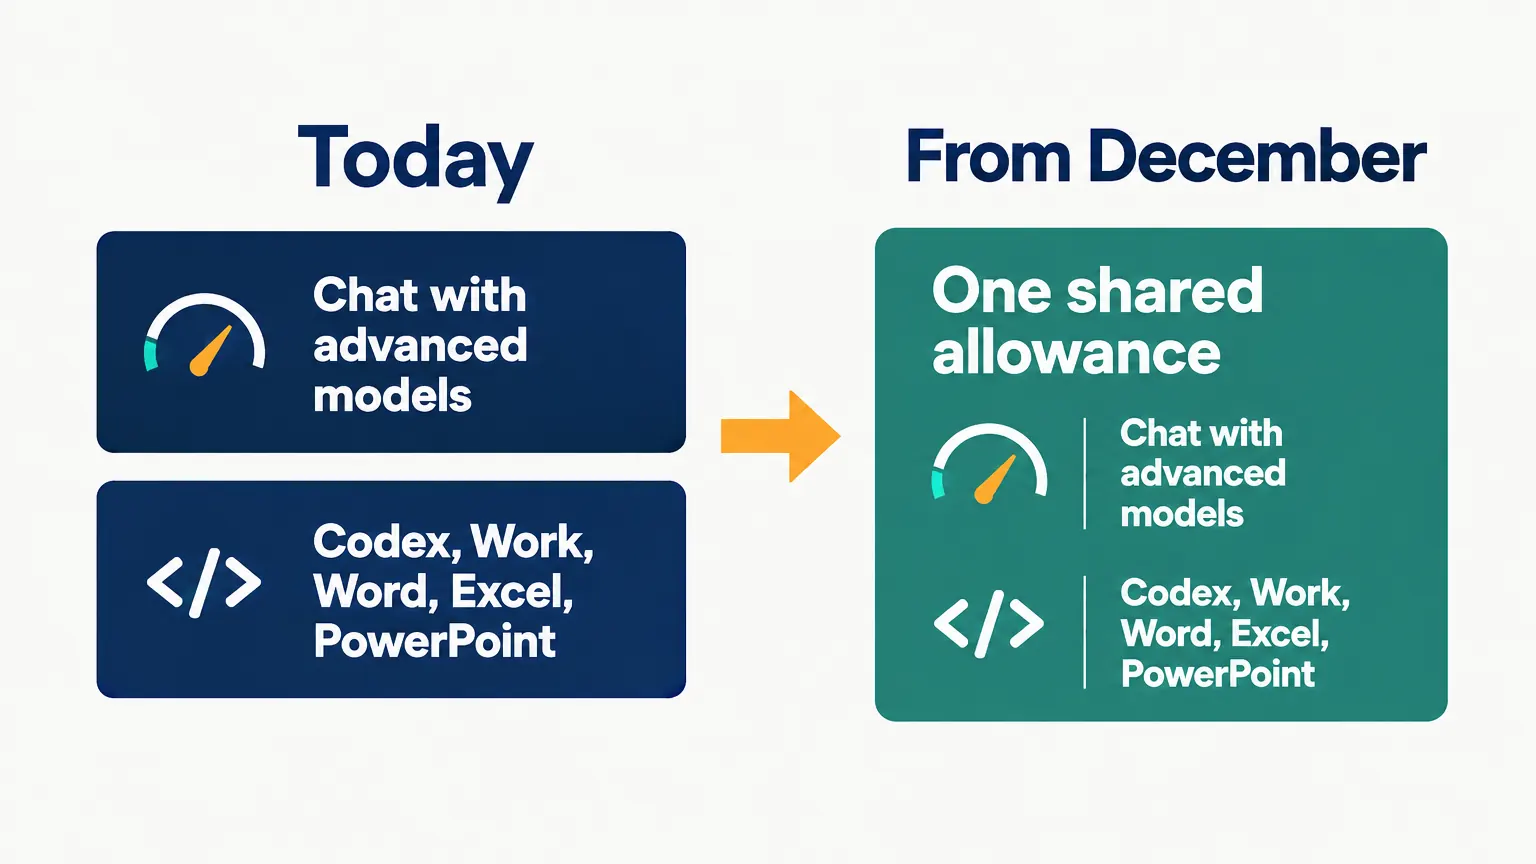
 On Plus and Pro, Work, Codex, Excel and PowerPoint already share one agentic allowance; December adds chat with the advanced models.
 Combined remaining usage and reset times will show in Settings, and at the cap you wait, upgrade or buy credits.
 OpenAI gives no exact date and no allowance sizes, and we found no blog or X post announcing the change.
§ 01What changes in December

| Question | Answer from OpenAI’s help page |
|---|---|
| Which plans | Plus, Pro and Business |
| What is shared | One usage allowance across ChatGPT and Codex |
| How it is measured | Tokens, the units a model reads and writes |
| What is exempt | Instant chat |
| Where to check | Settings, Usage: combined remaining usage and reset times |
| At the limit | Wait for the reset, upgrade the plan, or buy credits |
| When | December, no exact date |
“Your usage for ChatGPT and Codex will be measured in tokens, the units of information a model processes and generates.” That makes the cost of a request depend on what it asks for: “More advanced models and complex tasks generally use more of your allowance.” The one exception is the fast default model: “Instant chat will not draw from your usage.”
OpenAI also tries to settle nerves: “We expect most users won’t need to wait for their usage to reset more often than they do now.” When a user does run out, “you can wait for it to reset, upgrade your plan, or buy credits to continue using eligible features.”
§ 02What already shares, and what joins it
On personal plans, the pooling started before this. OpenAI’s credits page already says: “For Plus and Pro, Codex, ChatGPT Work, Excel, and PowerPoint can share the same agentic usage allowance when those features are available on your plan.” December folds chat with the advanced models into that pool, and leaves Instant out of it. Business seats on credit-based pricing already pay token rates for Work and Codex under OpenAI’s rate card.
| Use | Today | From December |
|---|---|---|
| Codex | Shared agentic allowance | One shared allowance |
| ChatGPT Work, Word, Excel, PowerPoint | Shared agentic allowance | One shared allowance |
| Chat with advanced models | Separate chat limits | One shared allowance |
| Instant chat | Separate | Does not count |
§ 03How much a token costs depends on the model
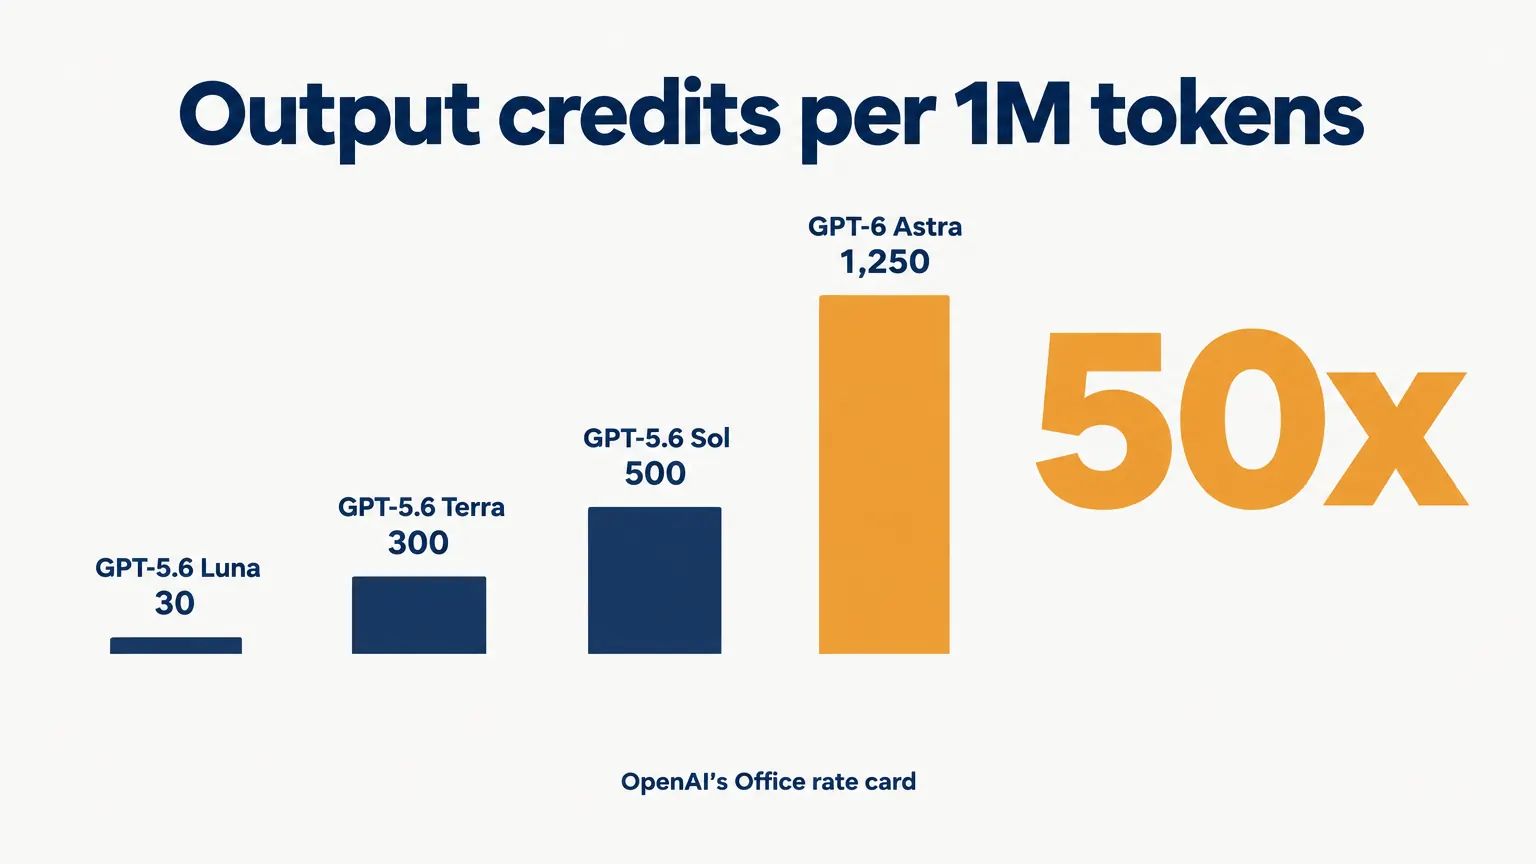
OpenAI has not said how the shared allowance converts tokens. The closest published guide is the rate card for its Office features, which already bill by the token on personal plans. There, output from GPT-6 Astra costs 1,250 credits per million tokens, 50 times GPT-5.6 Luna’s 30.
| Model | Input | Cached input | Output |
|---|---|---|---|
| GPT-5.6 Luna | 5 | 0.5 | 30 |
| GPT-5.6 Terra | 50 | 5 | 300 |
| GPT-5.6 Sol | 100 | 10 | 500 |
| GPT-6 Astra | 250 | 25 | 1,250 |
Read it as the shape of the spread, not the December math: these rates cover the Office features, and OpenAI has not published the size of the shared allowance on any plan.
§ 04What OpenAI has not said
- A date. The page says December and nothing more precise.
- Allowance sizes. No plan gets a number, and the page does not say whether the size changes.
- The conversion. How chat tokens and Codex tokens count against the same allowance is not on the page.
- Business details. Business is named, with no word on how seats on credit-based pricing change.
§ 05How heavy users took it
The first reactions came from people who use Codex all day. VraserX argued for keeping the limits apart: “Heavy Codex usage shouldn’t eat into your ChatGPT allowance.” LuminaBench went further: “if they make this feel terrible Anthropic can happily take my money”. The worry in both is the same: a long coding run now draws down the same balance as everyday chat.
§ 06Our read
Two days earlier OpenAI doubled Work and Codex usage on Pro; now it moves every paid plan to one pool, priced by what each request uses. Anthropic has been testing larger and smaller budgets on Claude Max at the same time. Token metering ties a plan closer to what each request costs the lab, and it means the model you pick now decides how far your plan goes.
CellCog’s AI employees run on Claude Opus 5.5. On CellCog you pay for the work, not the hire, and the cost depends purely on how much work you assign.
§ 07What we are watching
- A date and allowance sizes for each plan.
- A token rate card for chat models on personal plans.
- Whether the October 29 Pro doubling carries into the shared allowance.
§ 08Update log
As of November 1, 2026, 01:15 UTC: page opened from OpenAI’s help article (updated October 31), its credits and rate card pages, and reactions on X.
Q1When does the shared limit start?
OpenAI’s help page says December 2026 and gives no exact date.
Q2Which plans are affected?
Plus, Pro and Business. The help page does not mention Free, Go or Enterprise.
Q3Does every chat count against it?
No. Instant chat will not draw from the allowance. Chats with more advanced models will, and they use more of it.
Q4Will I hit the limit more often?
OpenAI says it expects most users won’t need to wait for a reset more often than they do now. It has not published allowance sizes.
Q5Where can I see my usage?
OpenAI says combined remaining usage and reset times will show in Settings, under Usage.