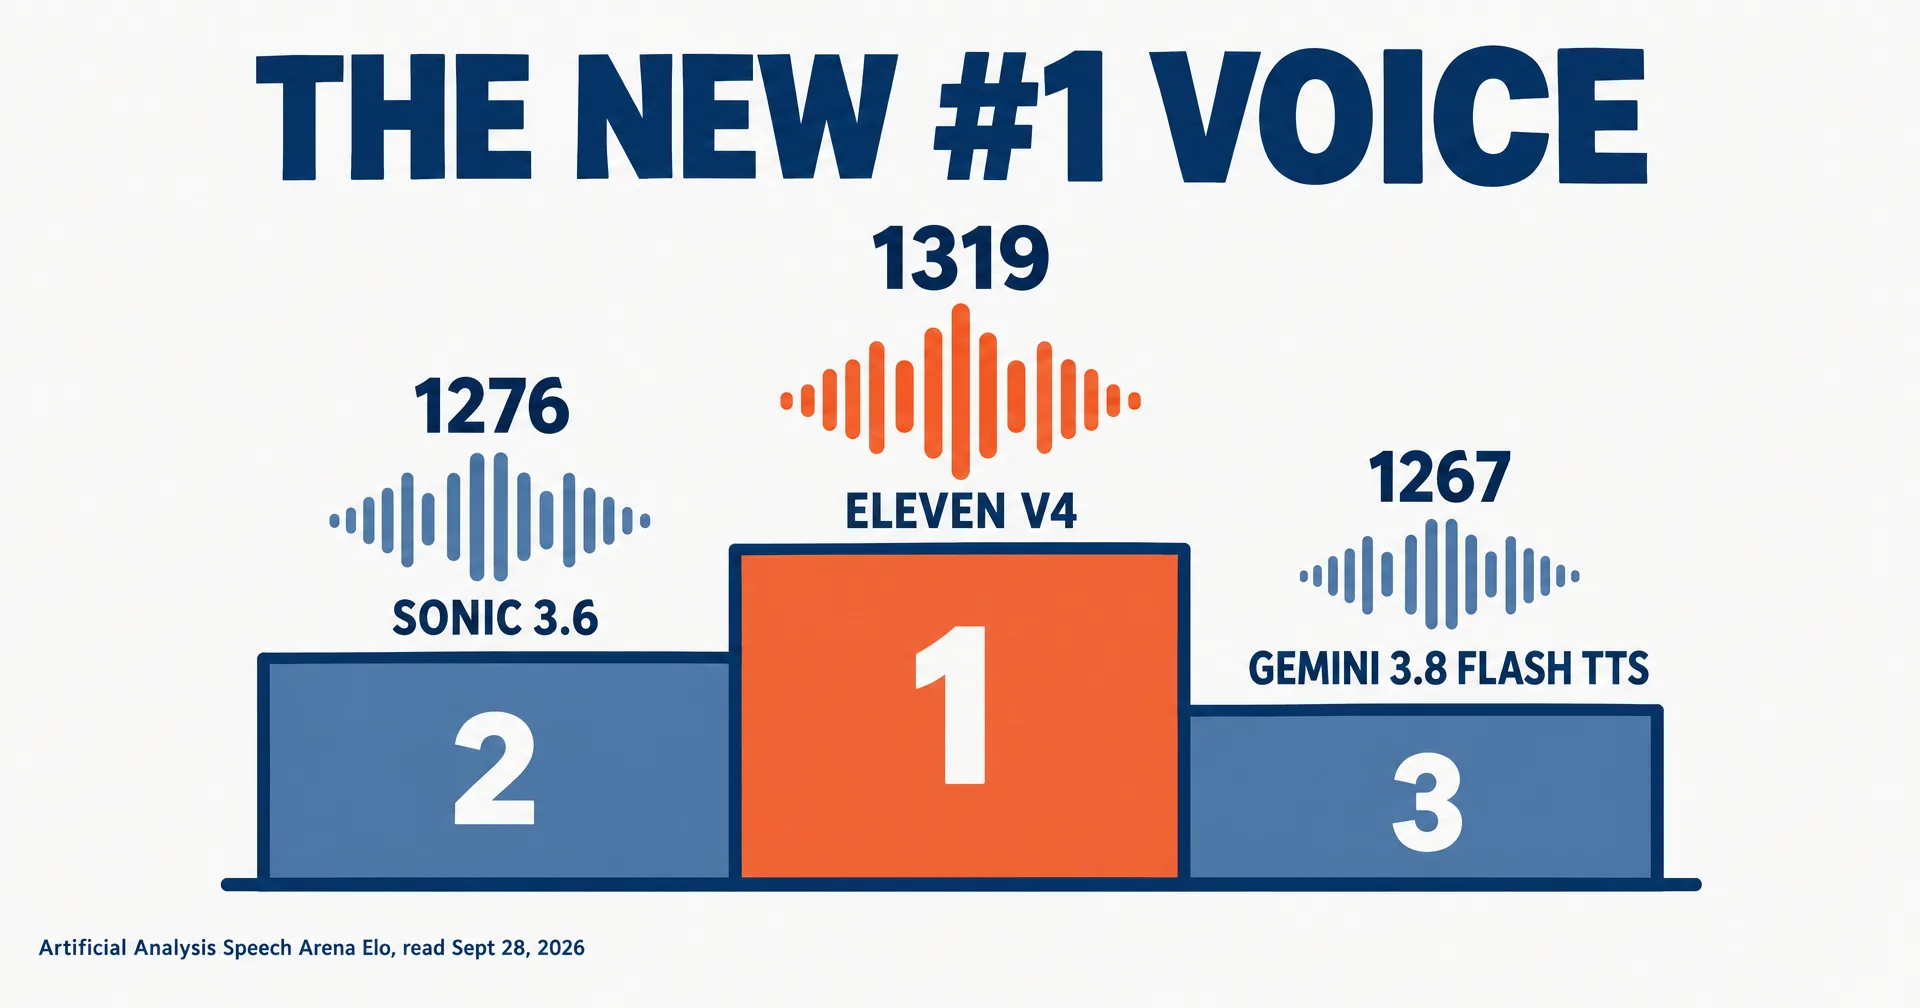
ElevenLabs has a new flagship voice. At 14:01 UTC on September 28, 2026, it launched Eleven v4 and Eleven v4 Turbo, “our fastest and most emotive voice models yet”, and by midday the model sat first on Artificial Analysis’s Speech Arena.
This page is read from ElevenLabs’ own posts, its pricing page and the Artificial Analysis board. Where ElevenLabs did not say something, we say so.
On this page · 7 sectionsOpen
- ElevenLabs launched Eleven v4 and Eleven v4 Turbo at 14:01 UTC on September 28, 2026, available at once in ElevenAgents, ElevenCreative and the API.
- Eleven v4 leads Artificial Analysis’s Speech Arena at an Elo of 1319, ahead of Cartesia Sonic 3.6 (1276) and Gemini 3.8 Flash TTS (1267), on the board read at launch.
- Eleven v4 Turbo is the low-latency version: a median inference latency of about 100 ms on ElevenLabs’ X post, and a median time to first speech of about 150 ms in its blog.
- Both models cover 90+ languages, take inline tags for delivery, emotion and sound effects, support IPA pronunciations, and make instant voice clones from 10 seconds of audio.
- For two weeks the API is 72% off: $22 per million characters for v4 (list $80) and $11 for Turbo (list $40), until October 12.
§ 01What ElevenLabs launched
Two models. Eleven v4 is the expressive one; Eleven v4 Turbo is “the low latency version of Eleven v4 with a median inference latency of ~100 ms, built for realtime use cases.” ElevenLabs’ blog adds a second latency figure for Turbo, a median time to first speech of about 150 ms. Both are “Available now in ElevenAgents, ElevenCreative and ElevenAPI.”
The features, per the launch thread and blog: inline tags for delivery, emotion, pacing and sound effects; better IPA pronunciation; multi-speaker dialogue that responds to what was just said; “coverage across 90+ languages, including Cantonese, Mongolian and Odia”; and instant voice clones “from just 10 seconds of audio”.
§ 02Where it ranks
| Rank | Model | Elo |
|---|---|---|
| 1 | Eleven v4 (ElevenLabs) | 1319 |
| 2 | Sonic 3.6 (Cartesia) | 1276 |
| 3 | Gemini 3.8 Flash TTS (Google) | 1267 |
| 4 | Qwen-Audio-3.0-TTS-Plus (Alibaba) | 1258 |
| 5 | Realtime TTS-2 | 1246 |
A 43-point lead is a clear first place on a blind-vote board. ElevenLabs also cites about 75% preference in its own head-to-head tests, which is its own measurement, not a third party’s.
§ 03What it costs
| Model | Launch price per 1K characters | List price per 1K characters |
|---|---|---|
| Eleven v4 | $0.022 | $0.08 |
| Eleven v4 Turbo | $0.011 | $0.04 |
The discount runs until October 12. At list price, Eleven v4 costs $80 per million characters, against $49 for Sonic 3.6 and $16.50 for Gemini 3.8 Flash TTS in the same Artificial Analysis table.
§ 04What ElevenLabs did not say
- Latency for v4 itself. The ~100 ms figure is for Turbo only.
- Price after October 12 for ElevenCreative plans. The free-v4 offer is framed as two weeks.
- An independent latency test. Both latency figures are ElevenLabs’ own.
§ 05Where CellCog sits
Our conflict, declared: CellCog’s speech and dialogue tools offer ElevenLabs as one provider, on Eleven v3 today, beside Gemini, OpenAI and MiniMax voices. We test a new voice model on our own pipeline before any switch, and Eleven v4 is now on that list. Our record of Kling 4.0, the video model announced the same day, sits next to this one.
§ 06What we are watching for
- Where Eleven v4 settles on the Arena once more votes land.
- Independent latency measurements for Turbo in live agents.
- The price once the discount ends on October 12.
§ 07Sources
- ElevenLabs on X, Eleven v4 launch thread, September 28, 2026, 14:01 UTC.
- ElevenLabs, Introducing Eleven v4, September 28, 2026.
- ElevenLabs, API pricing, read September 28, 2026, 16:35 UTC.
- Artificial Analysis, Text to Speech leaderboard, read September 28, 2026, 16:35 UTC.
Q1Is Eleven v4 the best text-to-speech model?
It leads Artificial Analysis’s blind-vote Speech Arena at Elo 1319 as of September 28, 2026, 43 points ahead of the next model. Arena rankings move as votes come in.
Q2What is the difference between Eleven v4 and v4 Turbo?
Turbo is the low-latency version built for realtime agents, with about 100 ms median inference latency; v4 is the most expressive model for narration, characters and dialogue.
Q3How many languages does Eleven v4 support?
90+, per ElevenLabs, including Cantonese, Mongolian and Odia.
Q4How long is the Eleven v4 discount?
Two weeks from launch, until October 12, 2026, per ElevenLabs’ pricing page. Creator plans and above also get v4 free in ElevenCreative, up to twice their monthly credits.
Q5Does CellCog use Eleven v4?
Not yet. CellCog’s speech and dialogue tools offer ElevenLabs as a provider on Eleven v3 today. We test new voice models on our own pipeline before switching.