We ran deep research on GPT Image 2.5 and Nano Banana 2.1 to learn which one wins at what, for our own image agent. Here it is, free: the same 24 prompts on both models, scored side by side on October 25, 2026, with the public leaderboards, the real cost per image and the limits that decide a choice before quality does.
The short version: GPT Image 2.5 won 9 prompts, Nano Banana 2.1 won 5, and 10 were ties. GPT Image 2.5 wins edits, transparent cutouts and product shots. Nano Banana 2.1 wins real places and objects it can look up, very wide banners and price per image. On posters, menus, photos and character consistency they are close enough that your brief should decide.
A disclosure: CellCog’s image agent has run both models since October 24, 2026, so we gain nothing if either one wins. We wanted to know when to pick which.
On this page · 15 sectionsOpen
- Who wins at what
- Text in images: a near tie, with one chart lesson
- Photorealism: it depends on the look you want
- Product shots: both catalogue-ready, one lighting slip
- Faithful edits: GPT Image 2.5 keeps the frame
- Transparent cutouts: only one model can
- Real-world accuracy: Nano Banana 2.1 looks things up
- Wide banners and 4K: Nano Banana 2.1 goes further
- Character consistency: a tie
- What each image costs
- What the public leaderboards say
- The limits that decide before quality does
- How CellCog picks between them
- How we ran the test
- Sources
 Across 24 prompts run side by side, GPT Image 2.5 won 9, Nano Banana 2.1 won 5 and 10 were ties; they averaged 4.71 and 4.29 out of 5.
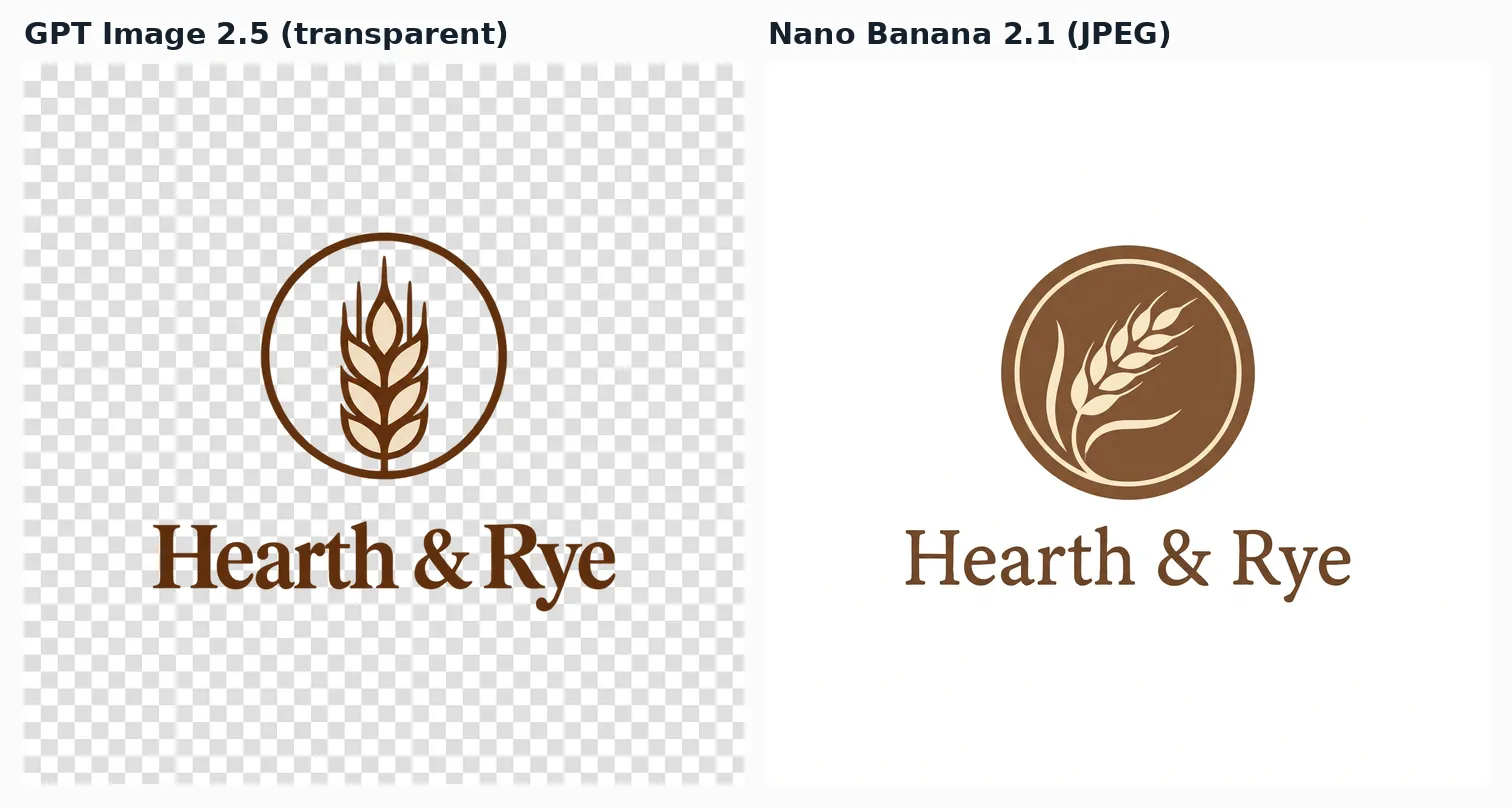
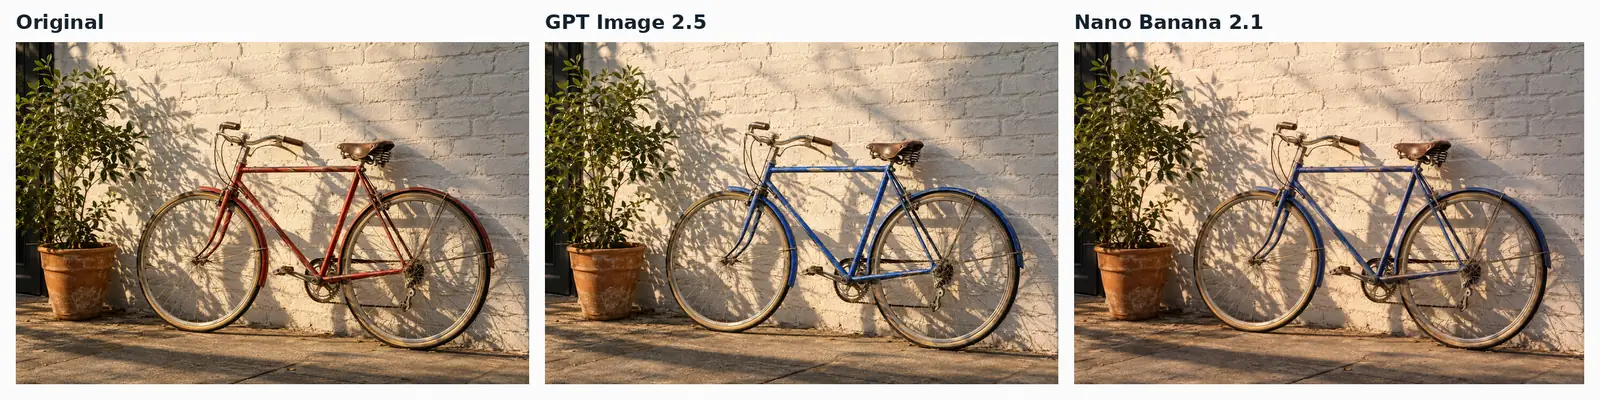
 GPT Image 2.5 won every faithful edit and every transparent cutout: it kept the original framing, and Nano Banana 2.1 cannot make a transparent background.
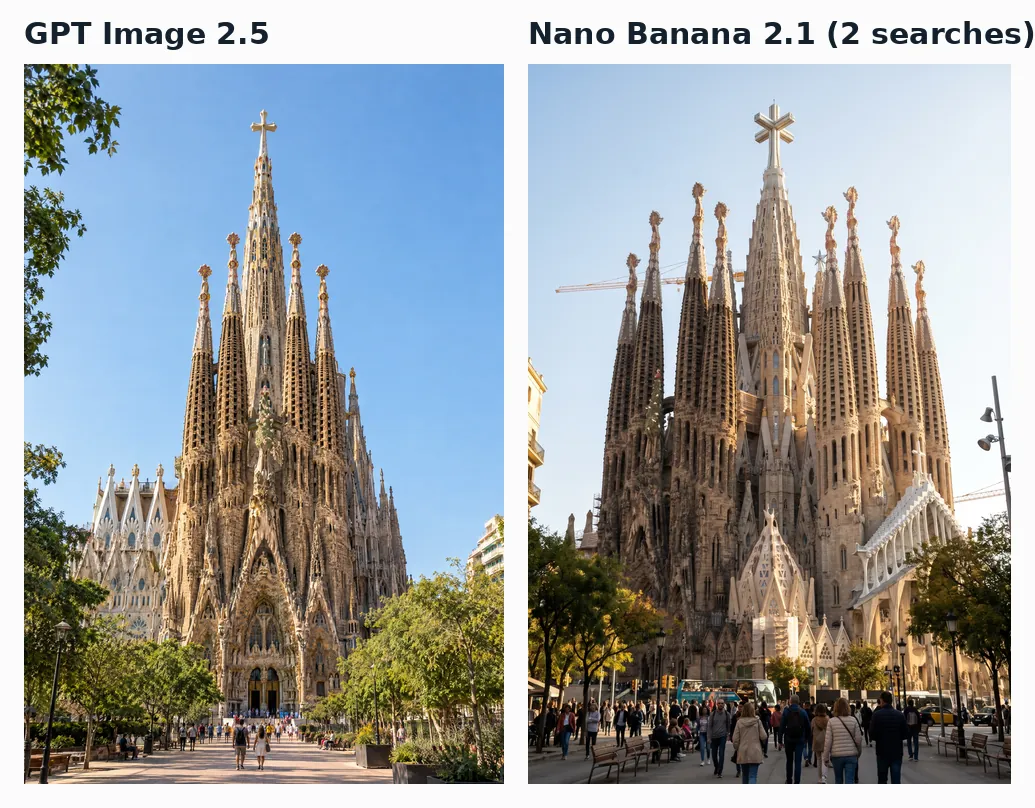
 Nano Banana 2.1 won on real-world subjects: it ran two Google searches before drawing the Sagrada Familia and drew more of the James Webb telescope’s real parts.
 Both charge $30 per million image tokens, but at high quality a 4 MP GPT image used 3,557 tokens ($0.107) and a 2K Nano image 1,680 ($0.050).
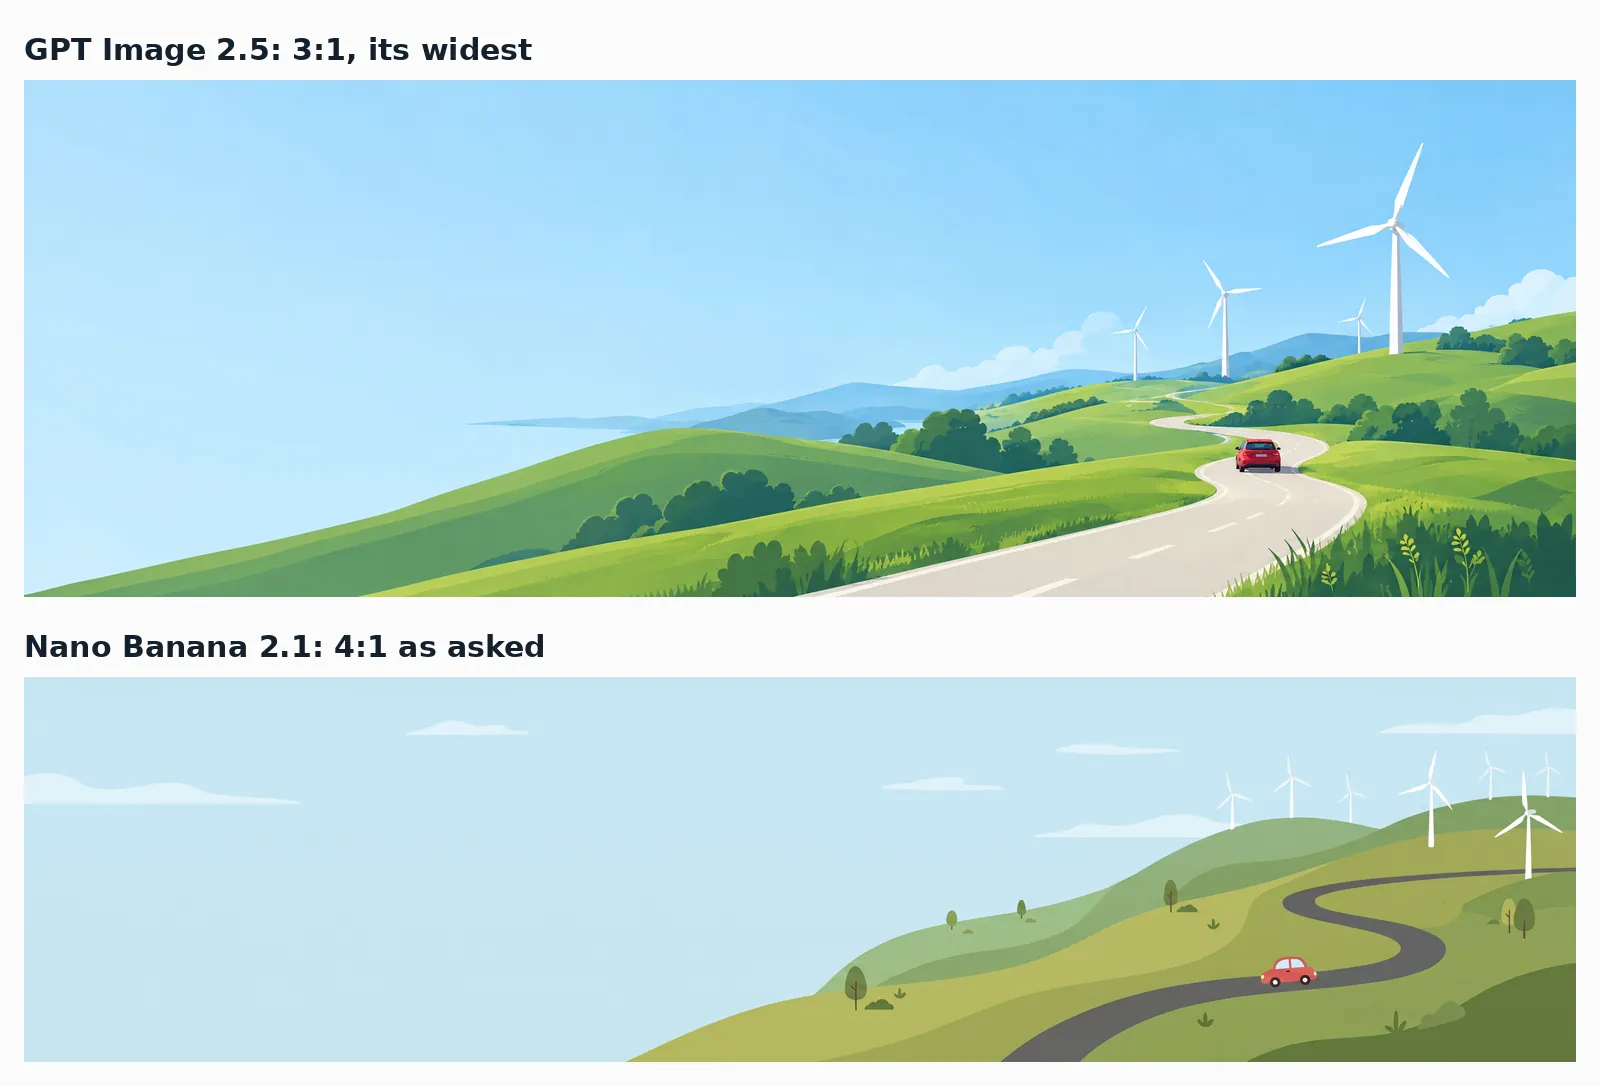
 Nano Banana 2.1 makes 4:1 and 8:1 banners and 4096 pixel squares; GPT Image 2.5 stops at 3:1 and 3,840 pixels on the long edge.
 Public boards agree on the order: Arena puts GPT Image 2.5 Sunburst at 1,425 and Nano Banana 2.1 at 1,328 on text-to-image (read October 25, 2026).
§ 01Who wins at what

| Category | Winner | GPT Image 2.5 | Nano Banana 2.1 | What decided it |
|---|---|---|---|---|
| Text in images | Nano Banana 2.1, narrowly | 4.67 | 5.00 | Both spelled every word; Nano drew the chart bars to scale |
| Photorealism | Tie | 4.67 | 4.67 | Nano’s portrait looked more like a real photo; GPT’s Tokyo signs were real Japanese |
| Product shots | GPT Image 2.5, narrowly | 5.00 | 4.67 | Nano put the perfume bottle’s shadow on the side facing the light |
| Faithful edits | GPT Image 2.5 | 4.67 | 3.33 | GPT kept the original framing; Nano reframed every edit |
| Transparent cutouts | GPT Image 2.5 | 5.00 | 2.00 | Nano Banana 2.1 returns JPEG only, so no transparency |
| Real-world accuracy | Nano Banana 2.1 | 4.33 | 5.00 | Nano searched Google before drawing the Sagrada Familia |
| Wide banners and 4K | Nano Banana 2.1, narrowly | 4.33 | 4.67 | Nano made the 4:1 banner GPT cannot; GPT labelled the 4K plate better |
| Character consistency | Tie | 5.00 | 5.00 | Both kept the same courier across three scenes |
| Result | Prompts |
|---|---|
| GPT Image 2.5 won | 9 |
| Tie | 10 |
| Nano Banana 2.1 won | 5 |
| Average score, GPT Image 2.5 | 4.71 |
| Average score, Nano Banana 2.1 | 4.29 |
The average gap is small, 4.71 against 4.29 out of 5, and most of it comes from one category: Nano Banana 2.1 cannot make a transparent background at all. Take transparency out and the two models score 4.67 and 4.62.
§ 02Text in images: a near tie, with one chart lesson
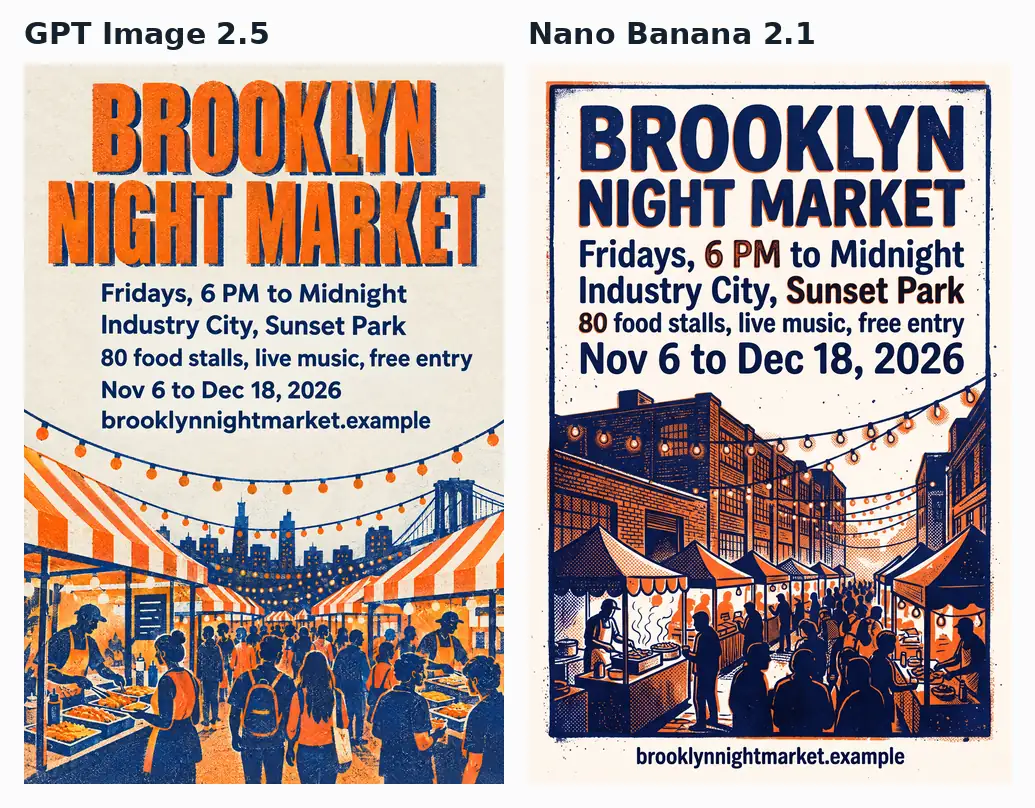
The poster prompt asked for six exact lines, including a date range and a web address. Both models spelled all six. Nano Banana 2.1 moved the address to a footer, which is a fair layout choice. The menu asked for a title, a subtitle and eight dishes with prices; both got every word and price right. GPT Image 2.5 right-aligned the prices, and Nano kept them inline as written.
The bar chart separated them. Both printed the right five labels and values, but only Nano Banana 2.1 drew the bars to scale. GPT Image 2.5’s bars ran about two points long on its own axis: Norway’s 89% bar ends near 91, and the United States’ 9% bar ends near 11. For a chart that has to be exact, draw it from the data and use either model for the illustration around it.
§ 03Photorealism: it depends on the look you want
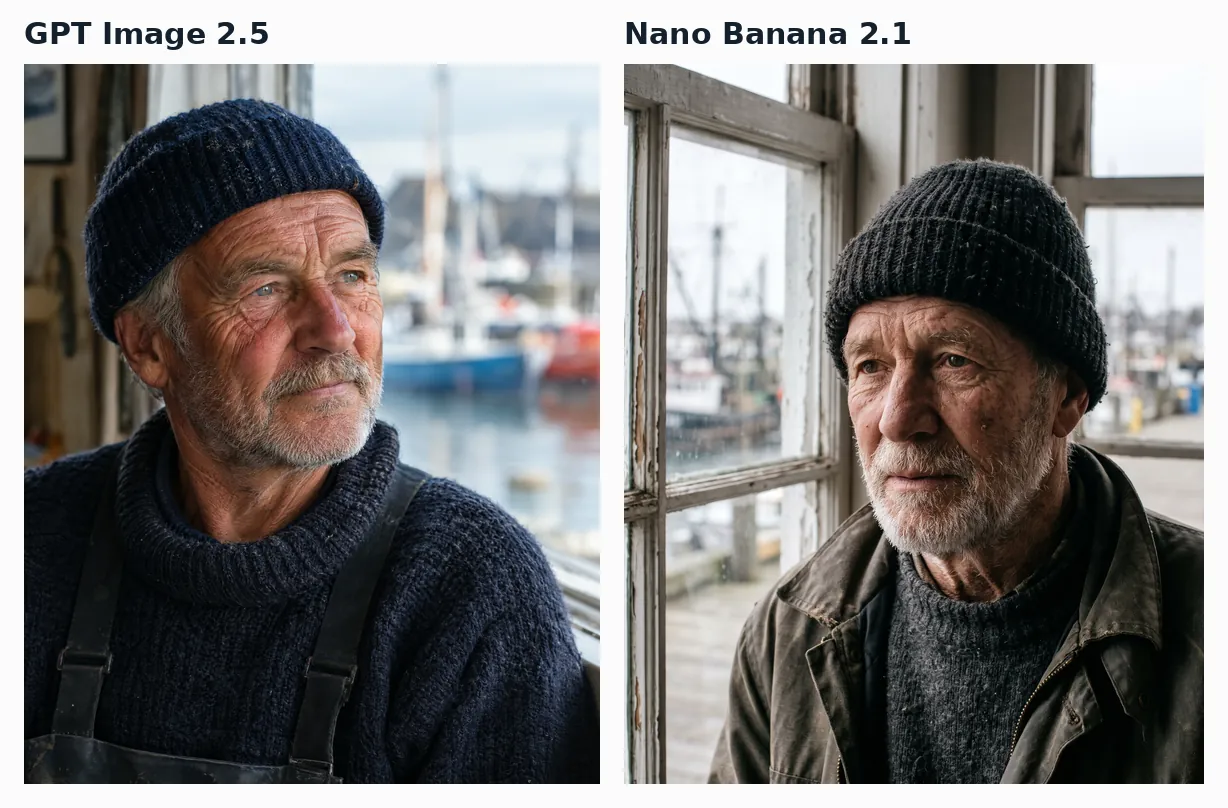
Nano Banana 2.1’s fisherman reads like a documentary photo: flat window light, a worn jacket, nothing polished. GPT Image 2.5’s is sharper, with heavier skin detail and a retouched, editorial look. The ramen bowls are both magazine-grade; each model added one prop we did not ask for (GPT wood-ear mushrooms, Nano a spoon and a cloth).
The Tokyo alley tipped the other way. GPT Image 2.5’s signs read as real Japanese words for yakitori, izakaya and oden. Several of Nano Banana 2.1’s signs mix real characters with invented ones. If the image will be zoomed in or seen by Japanese readers, that matters.
§ 04Product shots: both catalogue-ready, one lighting slip
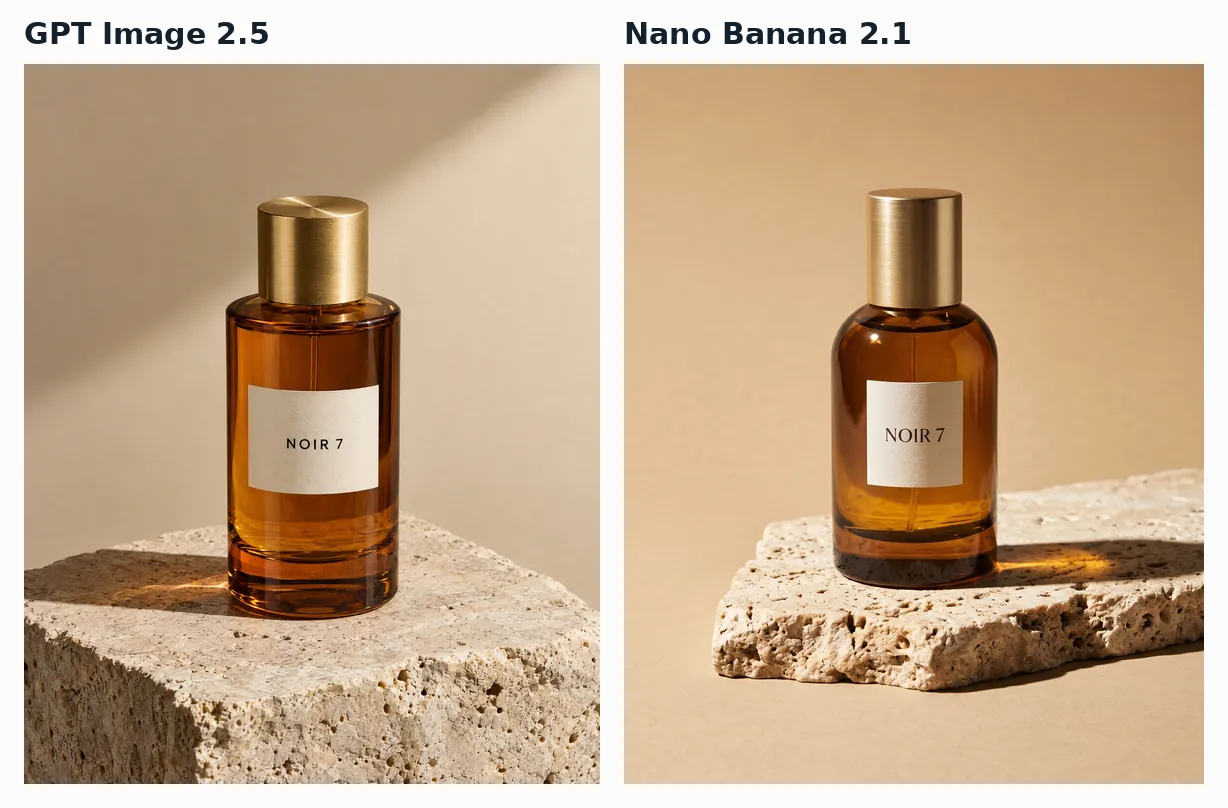
Both printed the NOIR 7 label exactly. We asked for one hard light from the upper right. GPT Image 2.5’s shadow falls left, away from the light, as it should. Nano Banana 2.1’s falls right, toward it; a photographer would reshoot it. The floating running shoe and the sage-green mug were ties: both kept the brief’s details, from no logos on the shoe to the embossed leaf on the mug.
§ 05Faithful edits: GPT Image 2.5 keeps the frame
We made three base photos with GPT Image 2.5, then asked both models to change one thing: recolour a bicycle frame, rewrite a chalkboard sign, and add a sleeping cat to a sofa. GPT Image 2.5 changed what we asked and left the wall, plant, shadows and framing almost untouched. Nano Banana 2.1 made each change correctly but reframed every photo, with a tighter crop and the subject larger.
The chalkboard was the closest call. All three outputs spelled CLOSED SUNDAYS. GPT Image 2.5 dropped the chalk underline that sat under the old text; Nano Banana 2.1 kept it. Nano’s cat was the most natural of the three. For an edit that has to drop back into a layout, GPT Image 2.5’s unchanged framing is the deciding feature.
We also ran each edit through Sunburst, OpenAI’s precision variant. On these three edits its output was nearly identical to Flare’s and took 32 to 33 seconds against 23 to 28 for Flare. That matches our September test: same tokens, same price, Sunburst slower.
§ 06Transparent cutouts: only one model can
GPT Image 2.5 returned a true transparent background for the bakery logo, the headphones and the robot sticker; the corner pixels have zero opacity. Nano Banana 2.1 cannot do this. Its API returns JPEG only, so it put each one on white. A background-removal step can fix that, but it is an extra step and the edges suffer. If you need a logo, a sticker or a product cutout, use GPT Image 2.5.
§ 07Real-world accuracy: Nano Banana 2.1 looks things up
Both resplendent quetzals match the real species: green crest, crimson belly, long tail coverts and white undertail. Both James Webb telescopes have 18 gold hexagonal segments and a secondary mirror on three struts; Nano Banana 2.1 also drew the solar array and the spacecraft bus, and its layered sunshield is closer to NASA’s renders.
The Sagrada Familia decided the category. Nano Banana 2.1 ran two Google searches before drawing (our tool logs them). It drew the crowned evangelist towers around a cross-topped central tower, with cranes still on site. GPT Image 2.5 drew a clean but generic cluster of spires. Each search adds $0.014 to Nano’s bill.
§ 08Wide banners and 4K: Nano Banana 2.1 goes further
The Manhattan panorama was a tie: GPT Image 2.5 made exactly 3360 by 1440, Nano Banana 2.1 made 3168 by 1344, and both put the Brooklyn Bridge on the left with lights on the river. The 4:1 website banner was not a contest. GPT Image 2.5 cannot go wider than 3:1, so the best it could give was 3840 by 1280. Nano Banana 2.1 delivered 4128 by 1024. GPT’s illustration was richer, but the shape was the brief.
For the 4K botanical plate, Nano Banana 2.1 made 4096 by 4096; GPT Image 2.5’s largest square is 2880 by 2880. Both spelled all four labels. GPT Image 2.5’s leader lines point at the right parts. Nano Banana 2.1’s midrib line points at the edge of the leaf, and it added a plate number with a stray glyph.
§ 09Character consistency: a tie
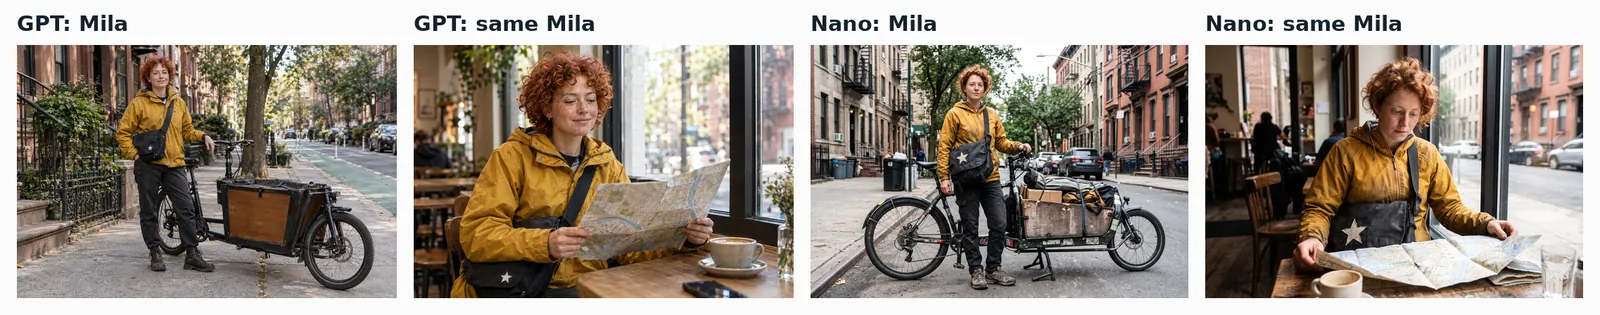
We described Mila, a courier with curly red hair, freckles, a mustard rain jacket and a black bag with a white star patch, then passed that first image back and asked for two new scenes. Both models kept her face, hair, jacket and bag across all three. Nano Banana 2.1 also kept the stickers and cargo on her bike; it invented a storefront sign in the rain scene.
§ 10What each image costs
Both models charge $30 per million image output tokens. The difference is how many tokens an image takes. Nano Banana 2.1 uses a fixed count per resolution. GPT Image 2.5’s count depends on size and quality; the figures below use our measured token tables at high quality, the setting we tested.
| Setting | Image output tokens | Cost per image | Cents per image |
|---|---|---|---|
| GPT Image 2.5, high, about 4 MP | 3,557 | $0.107 | 10.7 |
| GPT Image 2.5, high, 1024 square | 1,756 | $0.053 | 5.3 |
| GPT Image 2.5, high, 1536 by 1024 | 1,416 | $0.042 | 4.2 |
| Nano Banana 2.1, 2K | 1,680 | $0.050 | 5.0 |
| Nano Banana 2.1, 4K | 2,520 | $0.076 | 7.6 |
| Nano Banana 2.1, 2K with 2 Google searches | 1,680 | $0.078 | 7.8 |

For all 24 prompts, image output came to $2.08 on GPT Image 2.5 and $1.26 on Nano Banana 2.1 (prompt and text tokens excluded). At large sizes Nano Banana 2.1 costs about half. GPT Image 2.5 at medium quality is cheaper than both, $0.013 for a 1024 square in our September test, when the quality bar is lower.
Speed was close: a median of 28.7 seconds per image for GPT Image 2.5 at high quality and 30.7 seconds for Nano Banana 2.1 at 2K, measured end to end through our tool.
§ 11What the public leaderboards say
| Board | GPT Image 2.5 Sunburst | GPT Image 2.5 Flare | Nano Banana 2.1 |
|---|---|---|---|
| Arena text-to-image (board dated October 7, 2026) | 1,425 | 1,398 | 1,328 |
| Arena single-image edit (board dated October 19, 2026) | 1,514 | 1,481 | 1,426 |
| Artificial Analysis text-to-image | 1,222 (1st) | 1,207 (2nd) | 1,176 (4th) |
Every board puts both GPT Image 2.5 models ahead, by 97 points on Arena’s text-to-image board and 88 on its single-image edit board. Artificial Analysis ranks Nano Banana 2.1 fourth, behind GPT Image 2 too, and lists it at $33.6 per 1,000 images against $210.7 for GPT Image 2.5 at its max setting. Our test agrees on edits. It finds Nano ahead on things a crowd vote rarely tests: looked-up facts, wide shapes and price.
§ 12The limits that decide before quality does
| GPT Image 2.5 | Nano Banana 2.1 | |
|---|---|---|
| Widest canvas | 3:1 | 8:1 |
| Largest image | 3,840 px long edge, 2880 by 2880 square | 4096 by 4096 at 4K |
| Transparent background | Yes | No |
| Output formats | PNG, WebP, JPEG | JPEG |
| Reference images | Yes | Up to 14 (10 objects, 4 characters) |
| Looks things up while drawing | No | Google web and image search |
| Settings | Quality low, medium, high, xhigh, max | Resolution 1K, 2K, 4K |
| Image output price | $30 per 1M tokens | $30 per 1M tokens |
Read this table first. If you need transparency, there is one answer. If you need a 4:1 or 8:1 banner, there is one answer. Quality only decides when both models can do the job.

§ 13How CellCog picks between them
CellCog’s image agent runs GPT Image 2.5 by default, Flare at high quality, and switches to Sunburst when an edit must be precise. It picks Nano Banana 2.1 when an image needs a real-world lookup, a canvas wider than 3:1, a 4096 square or many reference images. This test backs that split. You describe the image; the agent picks the model and checks the result against your brief.
§ 14How we ran the test
- 24 prompts in 8 categories, 3 each, written for this test. Each model got the same prompt text.
- GPT Image 2.5 ran as Flare at high quality, at sizes matched to Nano’s 2K canvas (about 4 MP; 2880 square against Nano’s 4K). Nano Banana 2.1 ran at 2K, and 4K on the botanical plate.
- One render per prompt, no re-rolls.
- The edit base photos were made by GPT Image 2.5, which may favour it. Nano’s edits come back at its own 2K size, so we judged framing by content, not pixels.
- We scored each output 1 to 5 against the brief; the higher score won and equal scores tied.
- Costs count image output tokens only: GPT from our measured token tables, Nano from Google’s published counts.
- Times are wall clock from our tool; the first GPT image of each batch is excluded because its timer spanned a pause.
| ID | Category | Brief |
|---|---|---|
| 1 | Text | Night market poster, six exact lines |
| 2 | Text | Cafe menu, eight dishes with prices |
| 3 | Text | Bar chart, five labelled values |
| 4 | Photo | Fisherman portrait, 85mm, window light |
| 5 | Photo | Overhead tonkotsu ramen |
| 6 | Photo | Rainy Tokyo alley at night |
| 7 | Product | Perfume bottle, hard light upper right |
| 8 | Product | Floating running shoe, no logos |
| 9 | Product | Sage mug beside a pour-over |
| 10 | Edit | Recolour a bicycle frame |
| 11 | Edit | Rewrite a chalkboard sign |
| 12 | Edit | Add a cat to a sofa |
| 13 | Transparent | Bakery logo |
| 14 | Transparent | Headphones cutout |
| 15 | Transparent | Robot sticker |
| 16 | Real world | Resplendent quetzal |
| 17 | Real world | James Webb Space Telescope |
| 18 | Real world | Sagrada Familia today |
| 19 | Wide | Manhattan panorama at blue hour |
| 20 | Wide | 4:1 website banner |
| 21 | Wide | 4K botanical plate with labels |
| 22 | Consistency | Courier Mila, full body |
| 23 | Consistency | Mila at a cafe |
| 24 | Consistency | Mila riding in the rain |
§ 15Sources
- Arena, text-to-image leaderboard and single-image edit leaderboard, read October 25, 2026
- Artificial Analysis, text-to-image leaderboard, read October 25, 2026
- Google, Gemini API pricing
- CellCog, Nano Banana 2.1: price, Arena rank and what changed and GPT Image 2.5: Flare vs Sunburst, cost
Q1Is GPT Image 2.5 better than Nano Banana 2.1?
Narrowly. In our 24-prompt test GPT Image 2.5 won 9, Nano Banana 2.1 won 5 and 10 tied, and GPT leads Arena and Artificial Analysis. Nano wins lookups, wide banners and price.
Q2Is Nano Banana 2.1 cheaper than GPT Image 2.5?
At the sizes we tested, yes: $0.050 for a 2K image against $0.107 for a 4 MP GPT image at high quality. GPT at medium quality costs $0.013 for a 1024 square.
Q3Can Nano Banana 2.1 make transparent PNG images?
No. It returns JPEG only, so logos and cutouts come back on a white background. GPT Image 2.5 returns true transparency in PNG or WebP.
Q4Which model is better at text in images?
Both spelled a six-line poster and an eight-item menu exactly. On a bar chart Nano Banana 2.1 drew bars to scale, while GPT Image 2.5’s ran about two points long.
Q5Does CellCog use GPT Image 2.5 or Nano Banana 2.1?
Both, since October 24, 2026. GPT Image 2.5 is the default; the agent switches to Nano Banana 2.1 for real-world lookups, canvases wider than 3:1, 4K squares or many references.